We've created a LaTeX template here for you to use that contains the prompts for each question.
The homework requires Python 3.12. You do not need to install it yourself: the homework ships with a pyproject.toml pinned to 3.12, and uv sync (below) downloads that interpreter if it is missing. To confirm, run uv run python --version inside the homework directory after syncing.
Like previous assignments, we will use uv to set up the homework environment quickly.
Please refer to the official uv installation documentation for the most up-to-date installation instructions for your platform.
# Install uv once
curl -LsSf https://astral.sh/uv/install.sh | sh

# Optional: `uv` binary by default goes to `$HOME/.local/bin` on Linux/macOS,
# so you may need to add it to your PATH (uv may have done this for you):
export PATH="$HOME/.local/bin:$PATH"
# Install uv once
powershell -ExecutionPolicy ByPass -c "irm https://astral.sh/uv/install.ps1 | iex"
# Then open a NEW terminal window so that `uv` is on your PATH
# Download the homework zip and unzip into `hw4_mountaincar/`
# In your hw directory (it ships with a pyproject.toml pinned to Python 3.12)
uv sync                   # Create .venv, fetch Python 3.12 if needed, install gymnasium + numpy + matplotlib + pygame
uv run python grader.py   # Run the local grader
If you prefer typing python directly, activate the environment first with source .venv/bin/activate (on Windows: .venv\Scripts\activate) and drop the uv run prefix.
If you cannot run the assignment on your laptop or need additional computing resources, Stanford provides FarmShare, a community computing environment for coursework and unsponsored research. Please follow the instructions at https://docs.farmshare.stanford.edu/ to get started with the computing environment.
Markov decision processes (MDPs) can be used to model situations with uncertainty (which is most of the time in the real world). In this assignment, you will implement algorithms to find the optimal policy, both when you know the transitions and rewards (value iteration) and when you don't (reinforcement learning). You will use these algorithms on Mountain Car, a classic control environment where the goal is to control a car to go up a mountain. In the last problem, you will learn the policy directly with policy gradient, instead of learning Q-values.
In this problem, you will perform value iteration updates manually on a basic game to build your intuitions about solving MDPs. In this MDP, we have that:
Recall that the transition function $T: \text{States} \times \text{Actions} \rightarrow \Delta\text{States}$ (distribution over states) encodes the probability of transitioning to a next state $s'$ after being in state $s$ and taking action $a$ as $T(s, a, s')$.
In this MDP, the transition dynamics are given as follows: $\forall i \in \{-1, 0, 1\} \subseteq \text{States}$,
Think of this MDP as a chain formed by states $\{-2, -1, 0, +1, +2\}$. In words, action $a_1$ has an 80% chance of moving the agent backwards in the chain and a 20% chance of moving the agent forward. Similarly, action $a_2$ has a 70% chance of sending the agent backwards and a 30% chance of moving the agent forward. We will use a discount factor $\gamma = 1$.
The reward function for this MDP is:
$$\text{Reward}(s,a,s') = \begin{cases} 10 & \text{if } s' = -2, \\ 50 & \text{if } s' = +2, \\ -5 & \text{otherwise}. \end{cases}$$In computer science, the idea of a reduction is very powerful: say you can solve problems of type A, and you want to solve problems of type B. If you can convert (reduce) any problem of type B to type A, then you automatically have a way of solving problems of type B potentially without doing much work! We saw an example of this for search problems when we reduced A* to UCS. Now let's do it for solving MDPs.
Let us define a new MDP with states $\text{States}' = \text{States} \cup \{ o \}$, where $o$ is a new state. Let's use the same actions ($\text{Actions}'(s) = \text{Actions}(s)$), but we need to keep the discount $\gamma' = 1$. Your job is to define transition probabilities $T'(s, a, s')$ and rewards $\text{Reward}'(s, a, s')$ for the new MDP in terms of the original MDP such that the optimal values $V^*(s)$ for all $s \in \text{States}$ are equal under the original MDP and the new MDP.
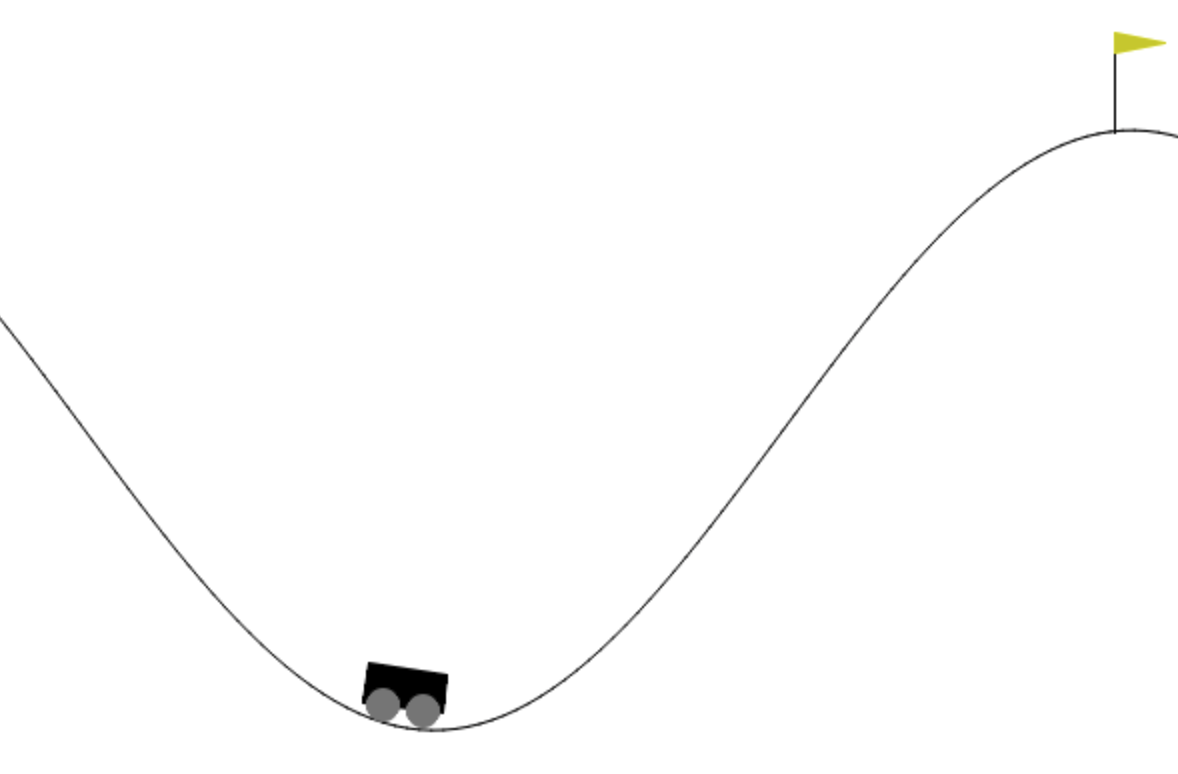
Hint: You can make $o$ an end state, so that its value is always 0. What recurrence must the optimal values for each MDP satisfy? You can show that the optimal values for each MDP are the same if these recurrences are equivalent. Revisit the MDP lecture to help you solve this problem.Now that we have gotten a bit of practice with general-purpose MDP algorithms, let's use them for some control problems. Mountain Car is a classic example in robot control [1] where you try to get a car to the goal located on the top of a steep hill by accelerating left or right. We will use the implementation provided by The Farama Foundation's Gymnasium, formerly OpenAI Gym.
The state of the environment is provided as a pair (position, velocity). The starting position is randomized within a small range at the bottom of the hill. At each step, the car can accelerate left, accelerate right, or do nothing, and the transitions are determined directly from the physics of a frictionless car on a hill. Every step produces a reward based on the car's distance from the goal and velocity.
First, install all the dependencies needed to get Mountain Car running in your environment, following the instructions at the beginning of this page. Note that we are using Python 3.12 for this assignment.
To get a feel for the environment, run an untrained agent that takes a random action at each step and see how it performs:
uv run python mountaincar.py --agent naive
You will see the agent struggling, not able to complete the task within the time limit.
In this assignment, you will train this agent with different reinforcement learning algorithms so that it can learn to climb the hill.
As the first step, we have designed two MDPs for this task. The first uses the car's continuous (position, velocity) state as is, and the second discretizes
the position and velocity into bins.
Carefully examine the ContinuousGymMDP and DiscreteGymMDP classes in util.py and make sure you understand them.
The starter code overview below summarizes what you need from each file.
If we want to apply value iteration to the DiscreteGymMDP (think about why we can't apply it to ContinuousGymMDP),
we require the transition probabilities $T(s, a, s')$ and rewards $R(s, a, s')$ to be known. But oftentimes in the real world, $T$ and $R$ are unknown,
and the gym environments are set up in this way as well, only interfacing through the .step() function. One method
to still determine the optimal policy is model-based value iteration, which runs Monte Carlo simulations to estimate $\hat{T}$ and $\hat{R}$, and then runs value iteration.
This is an example of model-based RL. Examine RLAlgorithm in util.py to understand the get_action and incorporate_feedback interface
and peek into the simulate function to see how they are called repeatedly when training over episodes.
You only modify submission.py, but you will use code from the other files. Here is what each file contains:
| File | What it contains |
|---|---|
submission.py |
Where you write your code: value_iteration (3a), ModelBasedMonteCarlo (3b), TabularQLearning (4a),
fourier_feature_extractor (4b), FunctionApproxQLearning (4c), ConstrainedQLearning (5c),
PolicyGradient (6c), and BootstrappedPolicyGradient (6f).
The docstrings and comments describe every argument and attribute you need. |
util.py |
The MDPs (NumberLineMDP, ContinuousGymMDP, DiscreteGymMDP), the RLAlgorithm interface,
simulate (the training loop), polynomial_feature_extractor (an example for 4b), and LinearValueFunction (used in 6f). |
train.py |
Trains an agent on Mountain Car and saves reward plots and the learned weights (3c, 4d, 5b, 6c-6g). |
mountaincar.py |
Shows an agent (random, or trained with train.py) driving the car. |
custom_mountain_car.py |
A copy of Gymnasium's Mountain Car environment whose max_speed can be changed (Problem 5). |
grader.py |
The local tests. Run uv run python grader.py for all tests, or uv run python grader.py 3a-0-basic for one. |
States and actions.
NumberLineMDP is the MDP from Problem 1 (used by the tests): states are the ints $-n, \ldots, n$ (Problem 1 has $n = 2$), and the actions are 1 ($a_1$) and 2 ($a_2$).DiscreteGymMDP (used in 3b and 4a): a state is a tuple of bin indices (position_bin, velocity_bin). With 20 bin edges per dimension there are 21 bins per dimension, so 441 states.ContinuousGymMDP (used in 4c, 5, and 6): a state is the NumPy array [position, velocity].0 (accelerate left), 1 (don't accelerate), and 2 (accelerate right).States and actions as array indices. The tabular algorithms store their values in NumPy arrays, so states and actions are converted to integer indices:
state_to_index(state), an integer in 0, ..., num_states - 1; index_to_state converts back.self.actions.index(action). For example, for NumberLineMDP,
action 1 has index 0 and action 2 has index 1.value_iteration takes transitions[s, a, s'] $= T(s, a, s')$,
rewards[s, a, s'] $= \text{Reward}(s, a, s')$, and an optional action mask valid_actions[s, a],
which is True if action $a$ can be taken in state $s$. A state with no valid actions is an end state: its value is always 0 and it has no optimal action.
ModelBasedMonteCarlo keeps arrays with the same layout, filled in from experience.The RL interface.
For each episode, util.simulate repeatedly calls rl.get_action(state, explore) to choose an action, takes that action in the MDP,
and then calls rl.incorporate_feedback(state, action, reward, next_state, terminal) so the algorithm can learn from it
(terminal is True if next_state is an end state). explore is True during training
and False during evaluation, when the agent should always act greedily. Each get_action starts by computing a local variable
exploration_prob that follows an exploration schedule (always explore for the first 20,000 steps, then explore with probability self.exploration_prob,
which the Q-learning agents in Problems 4 and 5 lower over time after 100,000 steps): use it instead of self.exploration_prob.
(This describes the agents in Problems 3-5; the policy gradient agent in Problem 6 works differently, as Problem 6 explains.)
value_iteration in submission.py. The starter code passes in dense NumPy tensors for the transition probabilities and rewards (shape (num_states, num_actions, num_states)) along with an optional action mask valid_actions describing which actions are available. Use vectorized NumPy operations to update the value function and return a NumPy array containing the optimal action for each state, given as its entry in action_ids rather than its index (store None whenever no action is available).
value_iteration function in submission.py.
submission.py, implement ModelBasedMonteCarlo which runs value_iteration
every calc_val_iter_every steps the agent takes. The learner keeps NumPy arrays of transition counts, accumulated rewards, and a boolean mask of tried actions,
and the provided first lines of incorporate_feedback already update them (using state_to_index to map raw states to indices). The get_action method controls how we use the latest policy as determined by value iteration,
and the rest of incorporate_feedback normalizes the arrays into transition and reward tensors and calls value iteration every calc_val_iter_every steps.
Implement the get_action and incorporate_feedback methods for ModelBasedMonteCarlo.
ModelBasedMonteCarlo in submission.py.
uv run python train.py --agent value-iteration to train the agent using the model-based value iteration you implemented above and see the plots of reward per episode. The command will run the training for three separate trials, so you will get three different training curves.
Each plot shows the reward of every training episode (blue) followed by 500 evaluation episodes in which the agent no longer explores (green).
Comment on the plots produced and discuss the performance. Also discuss what situations in general model-based value iteration could perform poorly.
You can also run uv run python mountaincar.py --agent value-iteration to visually observe how the trained agent performs the task now. The weights from the last trial will be saved and used for the task.
value_iteration or incorporate_feedback implementation.
In the previous question, we've seen how value iteration can take an MDP which describes the full dynamics of the game and return an optimal policy, and we've also seen how model-based value iteration with Monte Carlo simulation can estimate MDP dynamics if unknown at first and then learn the respective optimal policy. But suppose you are trying to control a complex system in the real world where trying to explicitly model all possible transitions and rewards is intractable. We will see how model-free reinforcement learning can nevertheless find the optimal policy.
(state, action) pairs. We learn the Q-value for each of these pairs using
the Q-learning update learned in class. In the TabularQLearning class, the Q-table is stored as a NumPy array of shape (num_states, num_actions). Implement the get_action method which selects
actions based on exploration_prob, and the incorporate_feedback method which updates the appropriate entry in that array using the provided indices (no Python dictionaries).
get_action and incorporate_feedback methods in TabularQLearning.
| 0 | $d_1s_1$ | $2d_1s_1$ | |
|---|---|---|---|
| 0 | 0 | $d_1s_1$ | $2d_1s_1$ |
| $d_2s_2$ | $d_2s_2$ | $d_1s_1 + d_2s_2$ | $2d_1s_1 + d_2s_2$ |
| $2d_2s_2$ | $2d_2s_2$ | $d_1s_1 + 2d_2s_2$ | $2d_1s_1 + 2d_2s_2$ |
fourier_feature_extractor in submission.py. Looking at util.polynomial_feature_extractor may be useful
for getting familiar with NumPy.
fourier_feature_extractor follows the same pattern as util.polynomial_feature_extractor, with two differences:
the array for dimension $i$ holds the multiples $[0, d_i s_i, 2 d_i s_i, \ldots, m d_i s_i]$ instead of powers, and the arrays are combined with an
outer sum (the table above) instead of an outer product. NumPy broadcasting computes an outer sum without loops: if a has shape
(n, 1) and b has shape (1, k), then a + b has shape (n, k), and
(a + b)[i, j] = a[i, 0] + b[0, j]. Flatten the result before combining it with the next dimension.
fourier_feature_extractor in submission.py.
(state, action) as the dot product of the state's features $\phi(s)$ with that action's column of weights in self.w.
Unlike the tabular Q-learning in which Q-values are updated directly, with function approximation, we are updating weights associated
with each feature. Using fourier_feature_extractor from the previous part, complete the implementation of FunctionApproxQLearning.
FunctionApproxQLearning using fourier_feature_extractor.
uv run python train.py --agent tabular and uv run python train.py --agent function-approximation to see the plots for how the TabularQLearning and FunctionApproxQLearning work respectively,
and comment on the plots. Similar to the previous part, the commands will run the training for three separate trials each. If none of your plots is converging to some values better than the initial reward, you should double check your implementation of incorporate_feedback. You should expect to see that tabular Q-learning performs better than function approximation Q-learning on this task. What might be some of the reasons?
You can also run uv run python mountaincar.py --agent tabular and uv run python mountaincar.py --agent function-approximation to visualize the agent trained with the discrete and continuous MDP respectively. The weights from the last trial will be saved and used for the task.
TabularQLearning and FunctionApproxQLearning
(for example, which reaches a higher evaluation reward, how quickly and how steadily each improves, and how consistent the three trials are),
discussing possible reasons for the difference as well.
FunctionApproxQLearning can be better in various scenarios.
We learned about different state exploration policies for RL in order to get information about $(s, a)$. The method implemented in our RL agents is epsilon-greedy exploration, which balances both exploitation (choosing the action $a$ that maximizes $\hat{Q}^*(s, a)$) and exploration (choosing the action $a$ randomly). $$\pi_{\epsilon\text{-greedy}}(s) = \begin{cases} \arg\max_{a \in \text{Actions}(s)}\hat{Q}^*(s,a) & \text{probability } 1 - \epsilon \\ \text{random from Actions}(s) & \text{probability } \epsilon \end{cases}$$
In real-life scenarios when safety is a concern, there might be constraints that need to be set in the state exploration phase. For example, robotic systems that interact with humans should not cause harm to humans during state exploration. Safe exploration in RL is thus a critical research question in the field of AI safety and human-AI interaction [3]. You can learn more about safe exploration in the past iterations' ethics contents.
Safe exploration can be achieved via constrained RL. Constrained RL is a subfield of RL that focuses on optimizing agents' policies while adhering to predefined constraints, in order to ensure that certain unsafe behaviors are avoided during training and execution.
Assume there are harmful consequences for the driver of the Mountain Car if the car exceeds a certain velocity. One very simple approach to constrained RL is to restrict the set of potential actions that the agent can take at each step. We want to apply this approach to restrict the states that the agent can explore in order to prevent reaching unsafe speeds.
self.max_speed parameter. Read through Gymnasium's Mountain Car implementation and explain how self.max_speed is used.
self.max_speed parameter is used in Gymnasium's Mountain Car implementation.
max_speed constraint by running uv run python train.py --agent function-approximation --max_speed=100000. We are changing max_speed from its original value of 0.07 to a very large float to approximate removing the constraint entirely. Ignoring the difference in the scale of the rewards accrued by the policy (because the rewards are designed to scale with max_speed), notice that running the MDP unconstrained doesn't really change the output behavior of the learned policy. Explain in 1-2 sentences why this might be the case.
(The plots are saved as fapprox_maxspeed_1.png to fapprox_maxspeed_3.png, so they don't overwrite your 4d plots.)
ConstrainedQLearning, implement constraints on the set of actions the agent can take each step such that the speed at the next time step stays below the threshold self.max_speed, i.e., $|\text{velocity}_{t+1}| <$ self.max_speed (when self.max_speed is None, every action is valid).
Remember to handle the case where the set of valid actions is empty: get_action should return None. Below is the equation that Mountain Car uses to calculate velocity at time step $t+1$ (the equation is also provided here).
$$\text{velocity}_{t+1} = \text{velocity}_t + (\text{action} - 1) * \text{force} - \cos(3 * \text{position}_t) * \text{gravity}$$
We've determined that in the mountain car environment, a speed of 0.055 or more is considered unsafe. After implementing the velocity constraint, run grader test 5c-helper (uv run python grader.py 5c-helper).
It trains two ConstrainedQLearning agents for 200 episodes each, one with a very large max_speed (so effectively unconstrained) and one with max_speed = 0.055,
and prints for each agent the maximum speed it reached and the number of episodes that ended early because no action was safe (get_action returned None).
If the constrained agent's maximum speed is 0.055 or more, double check your implementation.
ConstrainedQLearning in submission.py, then run uv run python grader.py 5c-helper.
Report the maximum speed and the number of episodes that ended with no safe action for both agents, and write 2-3 sentences: how the constraint changed the speeds,
how the car can reach a state where no action is safe, and what that suggests about one-step constraints. Only the written answer will be graded for this question.
Imagine a company is developing autonomous vehicles using RL and wants to train them on public roads in residential neighborhoods. These environments include pedestrians, other vehicles, and traffic signals, and the car’s onboard sensors (e.g., cameras) can detect these features.
In Problem 3 we estimated the MDP, and in Problems 4 and 5 we estimated Q-values. In this problem we will estimate the policy directly, using REINFORCE [4] from the policy gradient lecture. We will train a policy for Mountain Car, see why it needs a baseline, add bootstrapping, and compare the result with your Q-learning agents.
Our policy is a linear softmax over your Fourier features from 4b. With features $\phi(s) \in \mathbb{R}^d$ and a $d \times 3$ matrix $\theta$ (one column per action), the logits are $z = \theta^\top \phi(s)$ and $$\pi_\theta(a \mid s) = \frac{e^{z_a}}{\sum_{a'} e^{z_{a'}}}.$$ As in lecture, the utility of a rollout (one episode) $\tau = (s_0, a_1, r_1, s_1, \ldots, a_n, r_n, s_n)$ is $\text{utility}(\tau) = \sum_{t=1}^n \gamma^{t-1} r_t$ (what the plots call the discounted reward of an episode). After each rollout, REINFORCE with a baseline $b$ takes a gradient ascent step on the lecture's objective $$J(\theta, \tau) = \sum_{t=1}^n \log \pi_\theta(a_t \mid s_{t-1})\, \big(\text{utility}(\tau) - b\big).$$
get_action_probs, get_action, log_prob_gradient, and update_policy in PolicyGradient.
The agent samples its actions from $\pi_\theta$ in both training and evaluation, so get_action does not use explore.
log_prob_gradient returns your answer to 6a.
update_policy runs at the end of each rollout and takes one gradient ascent step on $J$, with step size $\eta$.
For the baseline we use a running average of past utilities: after each update of $\theta$, set $b \leftarrow b + \beta\, (\text{utility}(\tau) - b)$.
On the first rollout, when self.baseline is None, set $b = \text{utility}(\tau)$ before updating $\theta$.
Here $\theta$, $b$, $\eta$, and $\beta$ are self.theta, self.baseline, self.step_size, and self.baseline_step_size.
uv run python train.py --agent policy-gradient.
In rare cases a trial never reaches the flag; if that happens in one trial, rerun the command.
If none of your three trials has started improving by episode 400, double check your update_policy.
You can also run uv run python mountaincar.py --agent policy-gradient to watch the agent from the last trial.
get_action_probs on logits as large as $\pm 1000$,
that get_action returns one element of self.actions (not a list or an index),
and $\theta$ and $b$ after each rollout, including the first. Compute the whole update with $\theta$ from before the update.
uv run python train.py --agent policy-gradient --compare-baseline.
For each trial, it trains one agent with the baseline (blue) and one with $b = 0$ (red) from the same random seed, plots both,
and prints the average weight $\text{utility}(\tau) - b$ of the updates every 100 episodes.
Without the baseline, you should see the average weight stay hundreds below zero, and in at least one of your three trials that agent never learns to reach the flag.
Why can the agent without the baseline fail to learn, even though a baseline doesn't change the average update (as shown in lecture)?
uv run python train.py --agent policy-gradient --greedy-eval, which trains three agents and evaluates each one two ways:
by sampling from $\pi_\theta$, as in training (green), and by always taking its most likely action (orange).
You should see greedy evaluation do worse in at least two of your three trials, with some episodes timing out: running until the 1000-step time limit without reaching the flag.
Why does always taking the most likely action do worse than sampling?
util.LinearValueFunction, which learns with the same kind of update you wrote in 4c; the provided incorporate_feedback updates it after each rollout.
Implement update_policy in BootstrappedPolicyGradient so that it takes one gradient ascent step on this $J$, with step size $\eta$, as in 6c.
update_policy in BootstrappedPolicyGradient.
Use self.value_function.value(state) for $\hat{V}(s)$, and 0 for $\hat{V}(s_t)$ when the step's terminal is True.
The tests check $\theta$ after a rollout that ends at the flag and after one that ends at the time limit, with $\hat{V}$ held fixed.
As in 6c, compute the whole update with $\theta$ from before the update.
uv run python train.py --agent policy-gradient --bootstrap (it takes several minutes).
For each trial, it trains your tabular Q-learning (4a), function approximation Q-learning (4c), REINFORCE (6c), and bootstrapped policy gradient (6f)
from the same random seed, and plots their training curves together.
You should see the other three start improving before REINFORCE does.
Early in training, almost every episode times out.
Bootstrapped policy gradient samples its actions the same way as REINFORCE; only $J$ is different. Why does the bootstrapped agent start improving before REINFORCE?
[1] Moore. Efficient Memory-based Learning for Robot Control. 1990.
[3] OpenAI. Benchmarking Safe Exploration in Deep Reinforcement Learning.